Premium Indian
Speech Data for
AI That Understands.
Enterprise-grade Indian speech datasets for ASR, TTS, and Diarization training — verbatim & ground truth transcribed, speaker-separated, diarized, and fully consented. Built for teams who cannot afford noise in training data.
Everything your model needs to train on real speech.
Every dataset ships as a complete package — raw audio, verbatim & ground truth transcriptions, rich metadata, and speaker diarization. Nothing is missing.
Conversational Audio
Natural 2-speaker dialogues and read speech, recorded under VoIP conditions (WebRTC + dynamic mic). Both spontaneous conversations and scripted read-speech formats available — matched to your training requirements.
Ground Truth & Verbatim Transcriptions
Every dataset includes both verbatim transcriptions (every word exactly as spoken, including fillers and disfluencies) and clean ground truth transcriptions (<10% WER/CER guaranteed) — giving your model both raw realism and verified accuracy.
Speaker Separation & Diarization
Each recording is delivered as individual speaker tracks and a merged conversation file, with full diarization metadata — who spoke when, turn-level timestamps, and non-speaking gaps preserved. Ready for ASR, diarization, and dialogue model training.
Rich Metadata
Recording conditions, speaker profiles, domain tags, and session context included. Structured for direct ingestion into ML pipelines — no preprocessing overhead.
Explicit Contributor Consent
Every recording is covered by documented, explicit consent for AI training use. PII fully redacted. Legally clean for commercial model deployment globally.
Domain Customisation
Need data in healthcare, finance, e-commerce, or a niche vertical? We build domain-specific datasets to your specification — scripted or spontaneous formats.
NLU Annotation
Intent labeling and slot tagging on top of transcriptions — turning raw speech into fully annotated, NLU-ready training sets for dialogue AI and voicebot teams.
Built for every voice AI workload.
One Gold-Standard package. Three fully supported training verticals — and one on the way.
ASR Training
Fully SupportedTrain automatic speech recognition models on real conversational and read-speech Hindi audio. Ground truth transcriptions guarantee <10% WER/CER out of the box.
- Raw audio — 48kHz, 16-bit, mono
- Verbatim + ground truth transcriptions
- Speaker metadata & domain tags
- Turn-level diarization timestamps
TTS Training
Fully SupportedBuild natural-sounding Hindi voice synthesis models with consistent single-speaker read-speech recordings, clean ground truth text, and speaker-level acoustic metadata.
- Read-speech audio per speaker
- Clean ground truth transcription
- Speaker profile — age, gender, accent
- Consistent recording conditions per session
Speaker Diarization
Fully SupportedTrain or fine-tune diarization models with labelled 2-speaker conversational audio. Every file ships with who-spoke-when timestamps, separated speaker tracks, and a merged conversation file.
- 2-speaker dialogues with speaker labels
- Separated per-speaker tracks
- Turn-level start & end timestamps
- Merged conversation file included
NLU & Annotation
Coming SoonIntent labels, entity tagging, and domain-specific annotation layers on top of our existing transcribed audio. Built for conversational AI, voice assistants, and dialogue systems.
- Intent classification per utterance
- Entity tagging — locations, names, numbers
- Domain vocabulary coverage
- Verbatim base layer included
Studio-quality parameters. Production-ready format.
Every dataset is recorded, processed, and delivered to exact specifications. No guesswork on your end.
- Sample Rate48,000 Hz
- Bit Depth16-bit PCM
- ChannelMono (speaker-separated)
- Frequency Range14–16 kHz
- Recording MethodVoIP (WebRTC + Dynamic Mic)
- Noise HandlingReal-world conditions preserved
- LanguageHindi (Scaling)
- Conversation Type2-speaker dialogues
- Speaker Pool10 → 50+ within 1 week
- Transcription WER/CER<10% guaranteed
- PII RedactionFull — all recordings
- Quality ControlFull QC completed
Own it outright, or share the pool.
Choose how you access the data based on your competitive requirements and budget.
Shared Access
Access our standard dataset catalog. Ideal for research, benchmarking, or teams beginning to fine-tune Hindi speech models.
- Full transcriptions & metadata included
- Speaker-separated, 48kHz audio
- Consented for commercial AI training
- Shared licensing — other teams may also purchase
Full Ownership
Your dataset is recorded and reserved solely for you. No other party receives access to that data. Maximum competitive advantage.
- Exclusive rights — not sold to anyone else
- Custom domain, speakers & format
- Full metadata & scripted variants available
- Priority delivery & dedicated support
All licensing includes explicit contributor consent documentation. Pricing is volume-based — contact us with your hourly requirements for a quote.
We build the data your use case actually needs.
Don't compromise by adapting your model to generic datasets. Describe your domain, speaker demographics, conversation styles, and volume — we'll build a dataset precisely matched to your training requirements, complete with transcription and metadata.
- Domain-specific: healthcare, finance, e-commerce, telecom & more
- Custom speaker demographics & accent distribution
- Scripted or spontaneous conversation formats
- Scale to 50 speakers within one week, quality unchanged
- Delivered with ground truth transcriptions & full metadata
How It Works
- Share your requirements — domain, speaker count, accent type, conversation format, and volume.
- We scope and quote — a clear breakdown of timeline, cost, and deliverables within 48 hours.
- Recording & QC — speakers are briefed, recordings made, and each file passes full quality control.
- Transcription & metadata — human-verified transcriptions (<10% WER/CER) and structured metadata generated.
- Delivery — dataset packaged and delivered securely, with consent documentation included.
Clean data starts with clean consent.
As AI regulations tighten globally — EU AI Act, India's DPDP — provenance and consent documentation are no longer optional. Every DataCatalyst dataset is legally clean from day one.
A human behind every dataset.
DataCatalyst is a focused, founder-led operation — which means every dataset is built with direct accountability, not anonymised through layers of vendors.
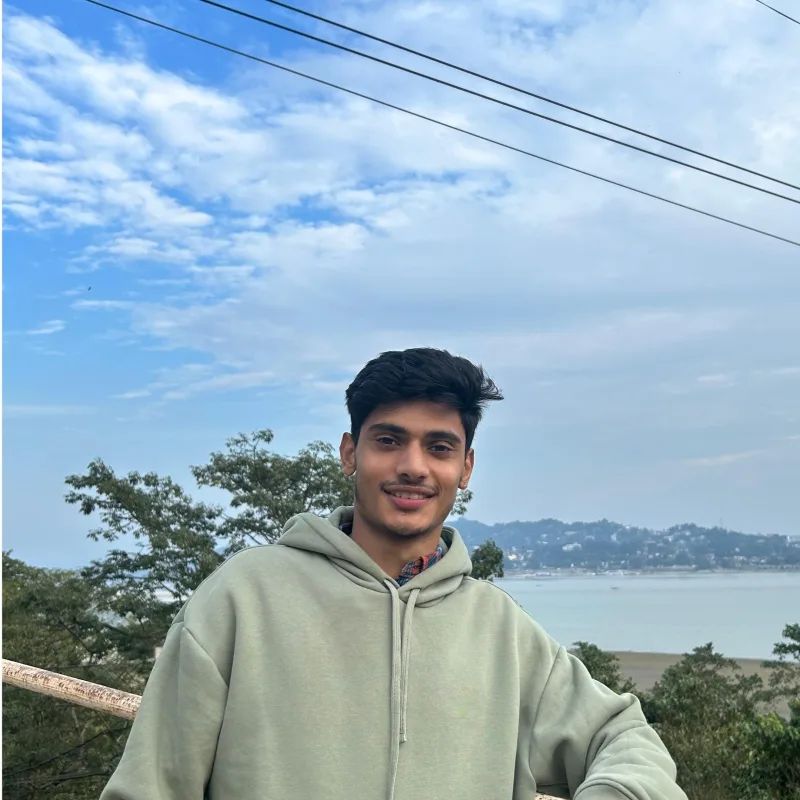
Divyam Bhatia
Founder & CEO, DataCatalyst.in
Divyam founded DataCatalyst to solve a problem he saw firsthand — the absence of high-quality, legally clean Hindi speech data for AI teams that need it most. Today, DataCatalyst delivers enterprise-grade conversational audio datasets with verified transcriptions, speaker separation, and explicit contributor consent. Every dataset ships under his direct oversight, with a standing commitment to <10% WER accuracy and full compliance documentation.
Hear the quality before you commit.
Request a free sample — a representative slice of our audio including 2-speaker dialogues, verbatim and ground truth transcriptions, speaker diarization, and full metadata. Evaluate the quality yourself before committing.
- 2-speaker dialogues — separated tracks + merged conversation file
- Ground truth transcription — human-verified, <10% WER/CER
- Verbatim transcription — every utterance captured exactly as spoken
- Speaker diarization — who spoke when, with turn-level timestamps
- 48kHz, 16-bit mono, fully QC'd audio
- Response within 48 hours — no commitment required